🚀 Merge Request: Integrate Language Detection Into Telegram Listener
Task: Integrate Language Detection into the main project
Issue: #2
Branch: feature/language-detection
📌 Summary
This merge request introduces automatic language detection into the Telegram bot workflow.
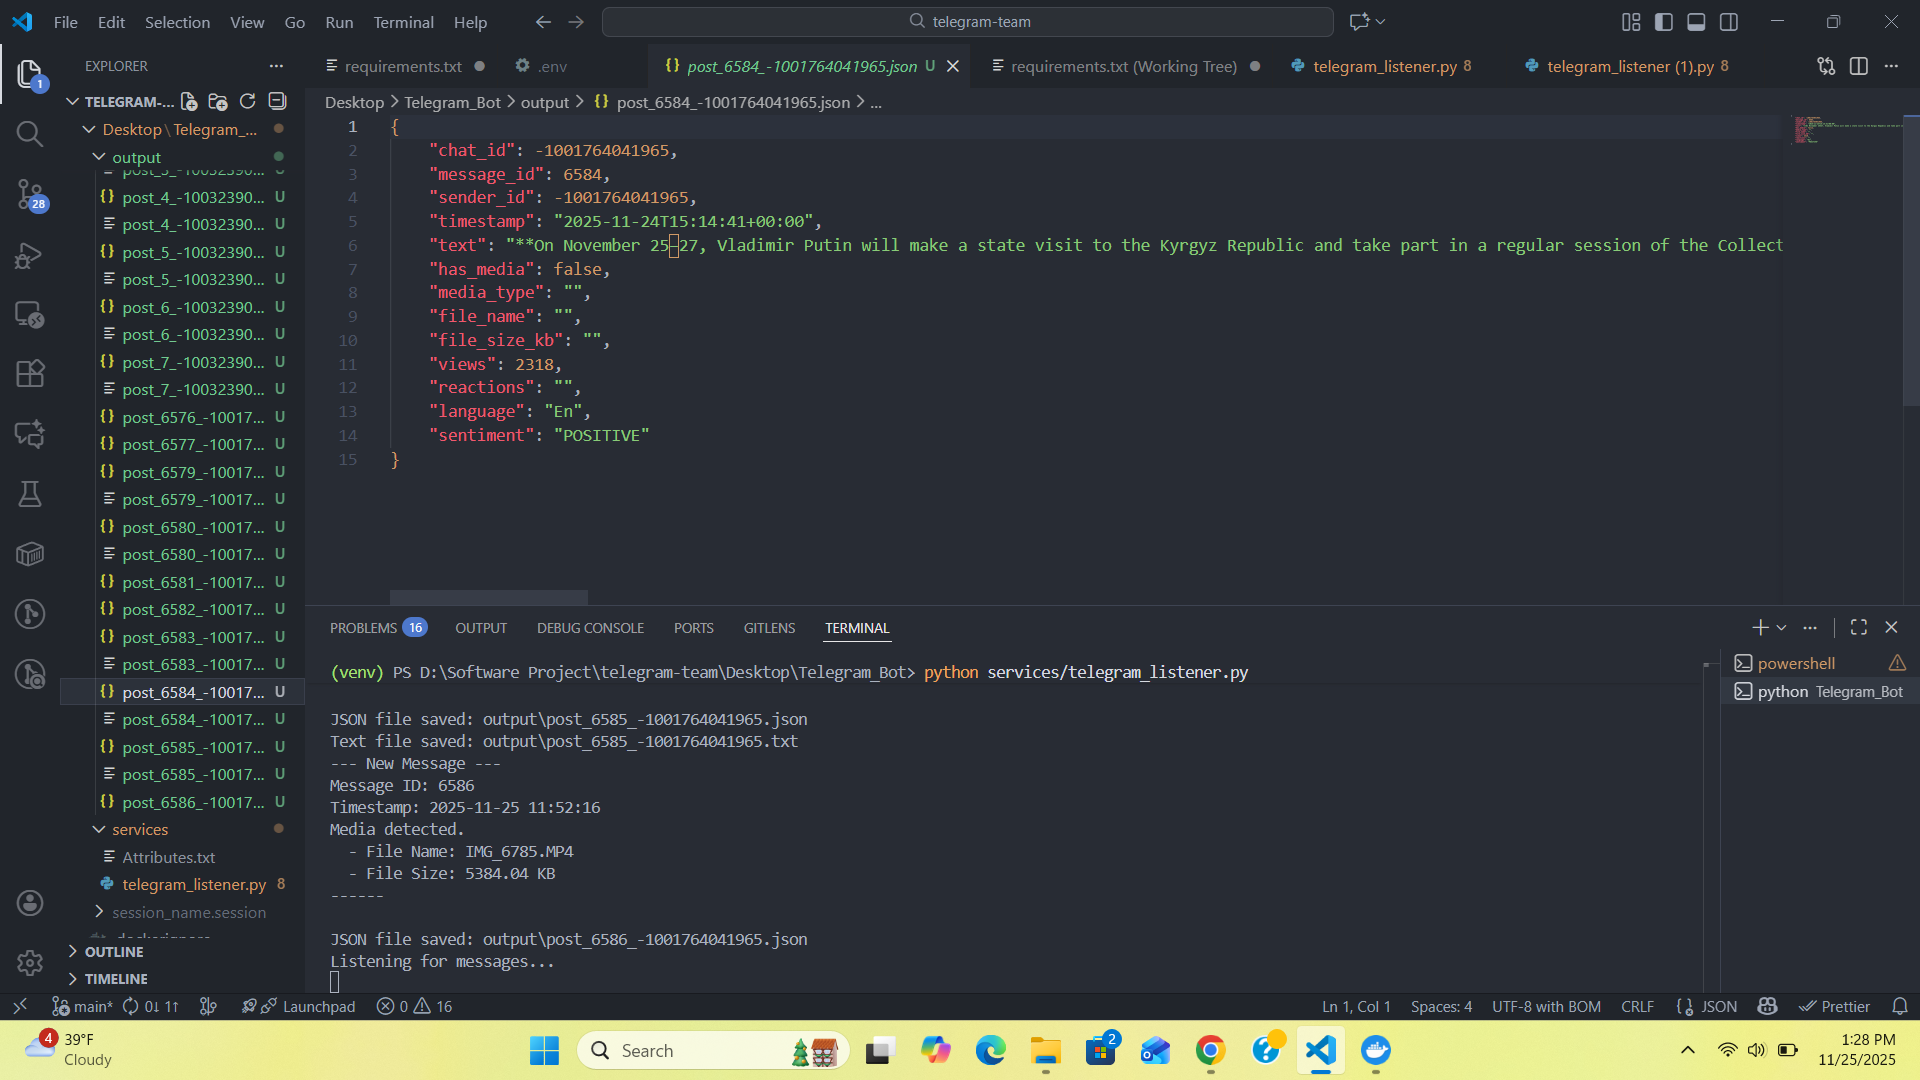
All incoming messages—text, captions, or media—are now analyzed for language, and this metadata is added to the JSON output files generated by the system.
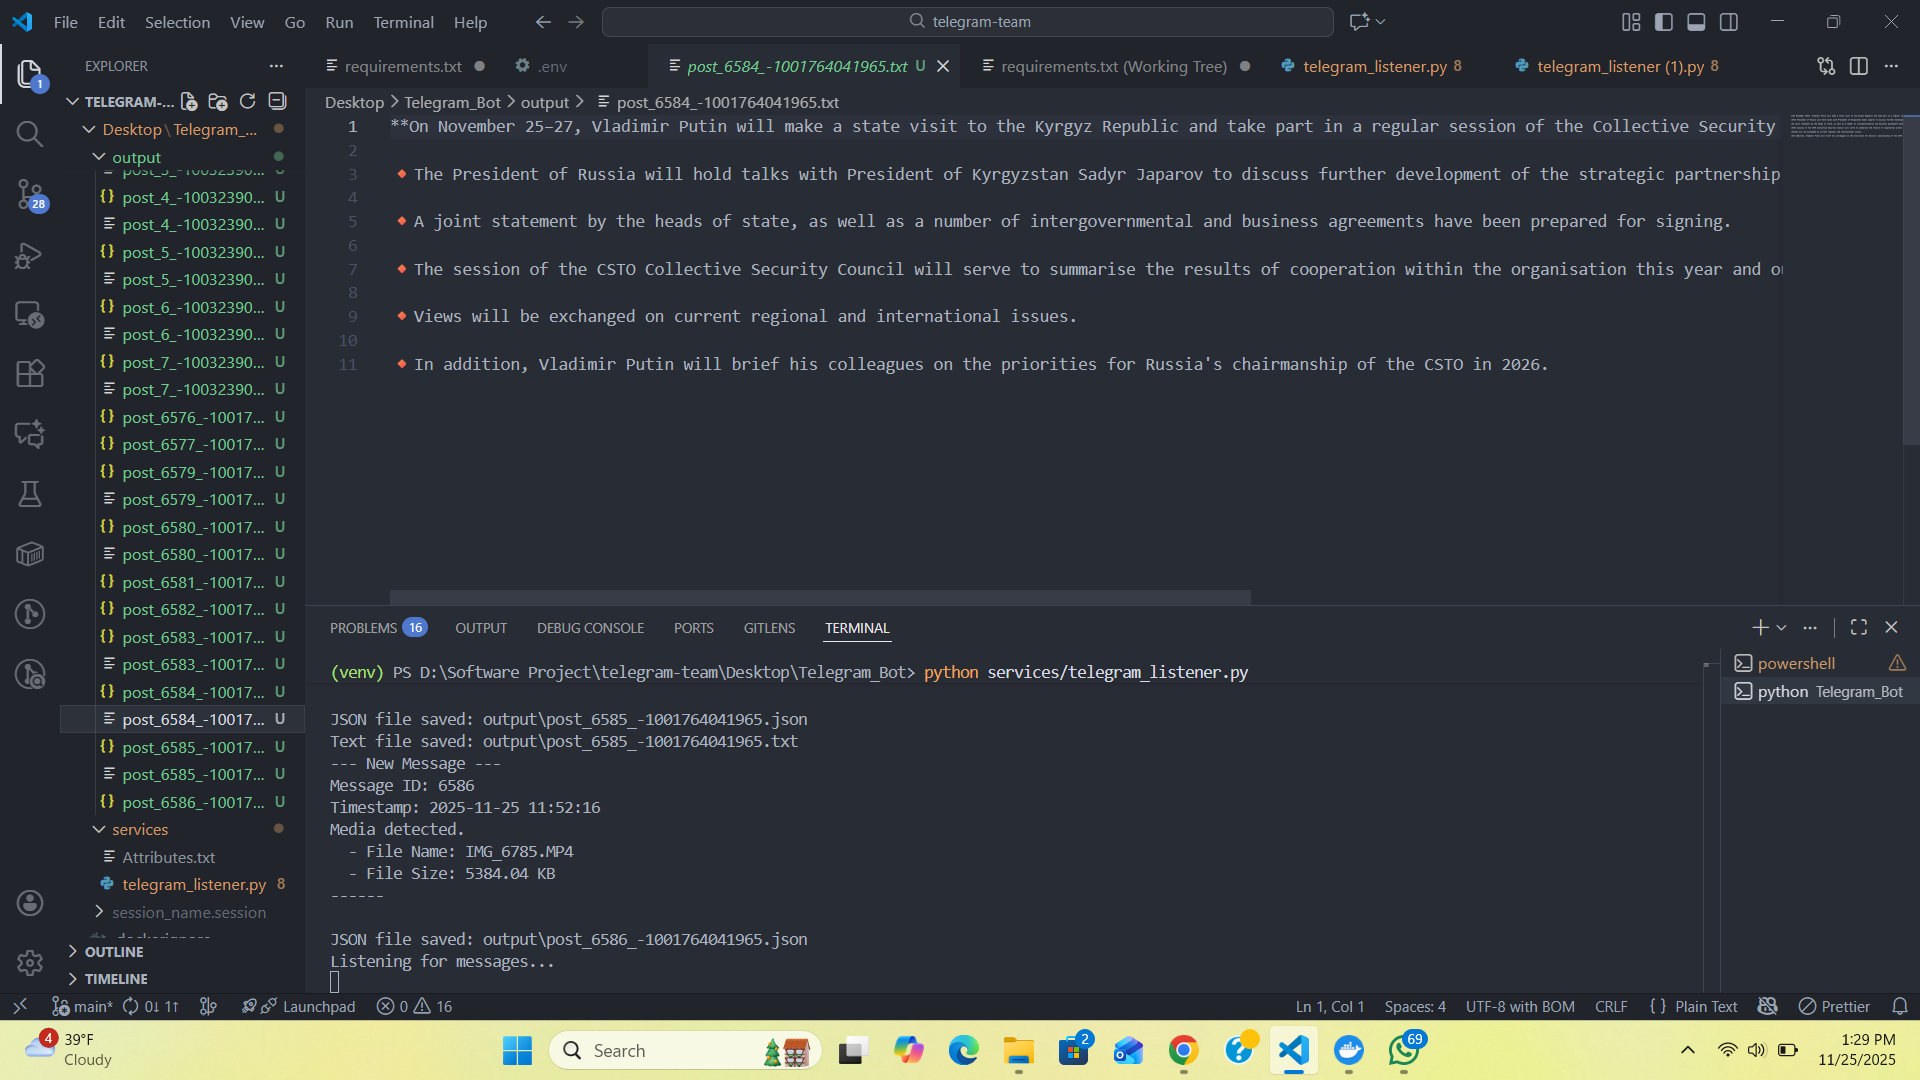
Running the listener now produces well-structured .json and .txt files inside the /output folder, enabling multilingual processing and more advanced analysis.
This enhancement prepares the project for broader NLP tasks and supports more sophisticated classification, threat assessment, and content evaluation.
📌 What Has Been Done
1. Language Detection Integration
- Added
langdetect. - Applied language detection to message text and media captions.
- Added
"language"field to JSON output. - Implemented safe fallback for undetectable language cases.
- Ensured sentiment analysis continues to run properly.
- Integrated the language field into both JSON and TXT file generation.
📌 Output Folder Generation
After running:
python services/telegram_listener.py
📌 Updated Dependencies
The requirements.txt file has been updated to support Python 3.13.9, which required specific compatible versions for core NLP libraries.
✅ Added
langdetect
🔄 Updated
-
transformers>=4.50.0,<5.0
✔ Compatible tokenizers build for Python 3.13 -
torch==2.9.1+cpu
✔ Official PyTorch CPU wheel available for Python 3.13
🧠 Reason for Changes
- Older versions were not compatible with Python 3.13.
- Prevents PyO3 + Rust tokenizers build failures.
Screenshots